Quillect · Document Intelligence Every field, every document, traced back to the page.
- Extract
- Validate
- Audit
- IDP at scale
Turn any document or scan into clean, validated, structured data — every value anchored to its exact place on the source page and cross-checked by a deterministic verifier.
- Page-anchored
- Every value linked to its source coordinates
- Cost-effective at scale
- Machine-speed throughput at a fraction of manual cost
- Immutable log
- Every action recorded for audit and replay
Why Quillect
Built so the output can be verified, field by field.
Evidence
Page-anchored values
Every field the model returns is linked to its exact bounding box and coordinates on the source page, so you can trace each value to its origin.
Control
Deterministic verification
A rule-based verifier cross-checks every field — arithmetic, format and master data — independently of the model, before the data reaches your systems.
Accountability
Immutable audit log
Every extraction, correction and approval is written to a tamper-evident log that supports full replay for audit.
How it works
How Quillect runs.
/ 01
Extract
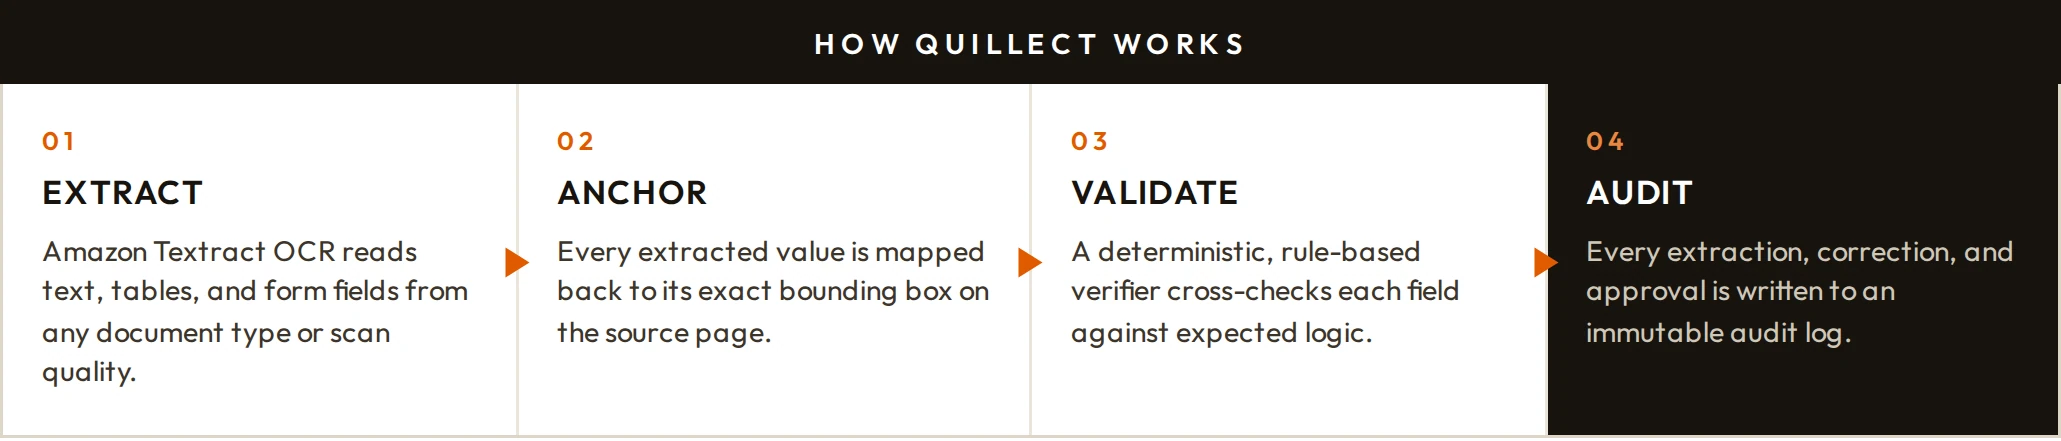
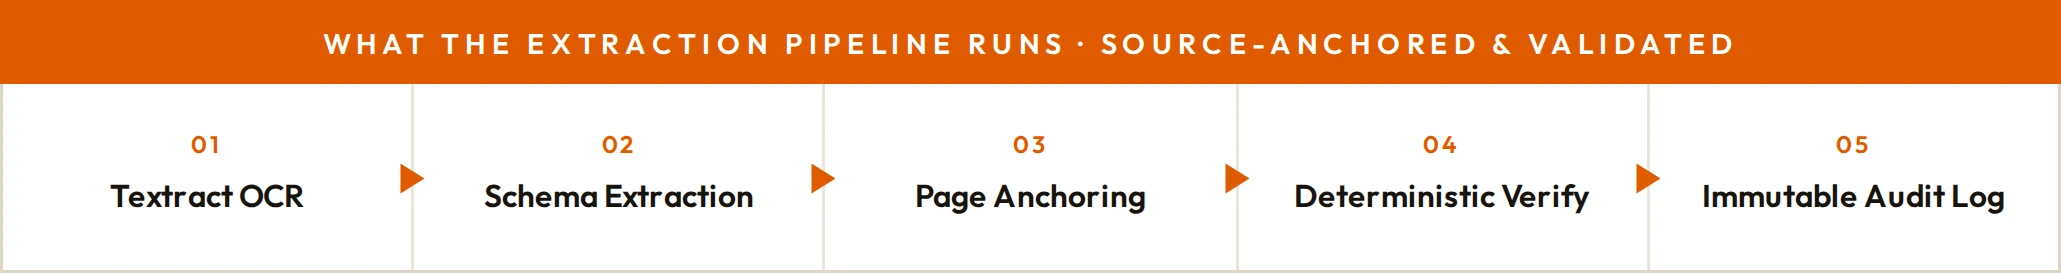
Amazon Textract OCR reads text, tables and form fields from any document type or scan quality.
/ 02
Anchor
Every extracted value is mapped back to its exact bounding box on the source page.
/ 03
Validate
A deterministic, rule-based verifier cross-checks each field against expected logic.
/ 04
Audit
Every extraction, correction and approval is written to an immutable audit log.
See it on your own data
Watch Quillect work on a real use case, in a 30-minute live demo.
Free. Then a scoped proof of concept at no cost, before you commit.
Inside the solution
Quillect, drawn out.
What you get
Outcomes you can hold us to.
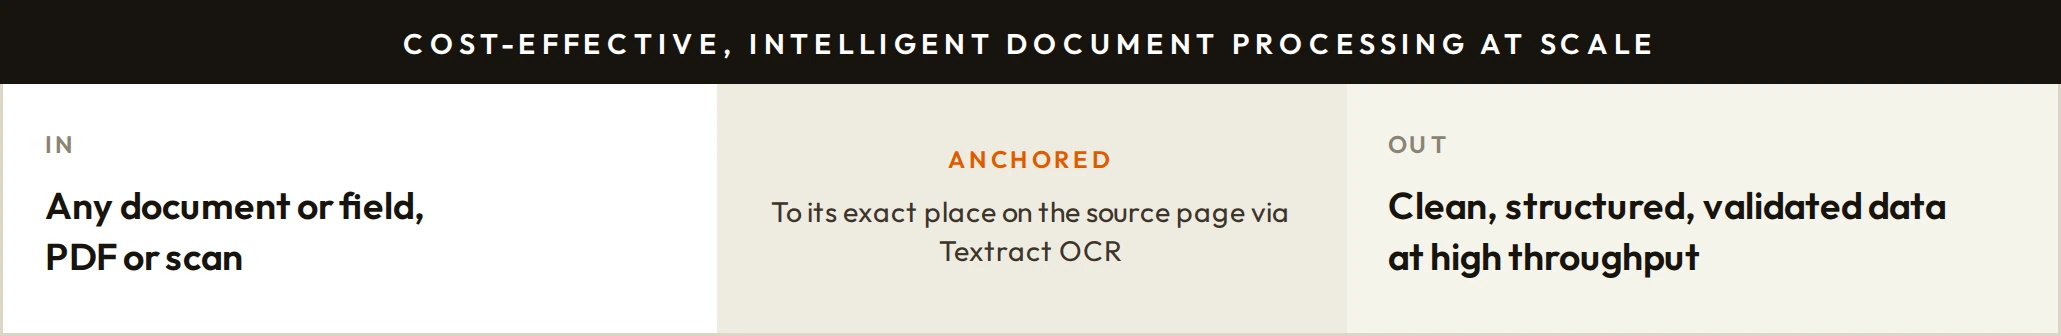
Any document or field — PDF or scan — turned into clean, structured data
Every value anchored to its exact coordinates on the source page
A deterministic verifier checking arithmetic, format and master data
Machine-speed throughput at a fraction of manual processing cost
An immutable, tamper-evident log of every extraction, correction and approval
Full replay for audit, field by field
Built for
- Shared services & operations heads
- Finance & AP leaders
- Banking, insurance & NBFC ops
- Logistics & trade documentation teams
Industries
- All industries
Works with
- Amazon Textract
- PDF & scans
- Master data
Free demo and no-cost proof of concept
Send us a sample set and see extraction on your own documents.
One document type · your sample set · no cost
The scope
- You pick one document type and send a representative sample
- We configure extraction, verification rules and the field schema
- You see page-anchored output and the verifier’s findings, field by field
You provide
- A sample set of one document type (redacted is fine)
- The target field schema, or your current manual template
- A contact who knows the current exception cases
You get
- Structured output for your sample, with every field page-anchored
- A field-level accuracy and exception report
- A throughput and cost-per-document estimate at your volume
FAQ · Deployment, data and cost
What buyers ask before they commit.
Have a question that is not answered here?
01How do we know the extracted values are right?
Two independent mechanisms. Every value is anchored to its bounding box on the source page, so a person can verify it in one click, and a deterministic, rule-based verifier cross-checks arithmetic, format and master data before the data reaches your systems.
02Does it work on scans and poor-quality documents?
Yes. OCR handles scans, and page anchoring means low-confidence fields are flagged with the exact region to check, rather than silently guessed.
03What makes it cost-effective at scale?
Pages are processed in tiers rather than all going through the heaviest model, so throughput is machine-speed at a fraction of manual cost. The proof of concept (PoC) gives you a cost-per-document estimate at your actual volume.
04Can we satisfy an auditor with this?
That is the design point. Every extraction, correction and approval is written to a tamper-evident log that supports full replay, and every value traces back to a coordinate on a page.
05Where does it run?
In your cloud or ours, whichever your security review prefers. OCR runs through Amazon Textract in the region you nominate.
06What can it change without us?
Nothing downstream. Extracted data reaches your systems only after the deterministic verifier passes it and, where you require it, a person approves it.
07Is our data used to train models?
No. Your documents are processed to produce your output. They are not used to train or fine-tune anything.
08What does it cost after the sample run?
The sample run is free and returns a cost-per-document estimate at your volume. Production is priced per document, not per seat.
More solutions
10+ agentic solutions. One standard.
Spend & Sourcing Analytics
Agentic Sourcing Foundation
One governed spend foundation on your SAP data, with specialised AI agents for sourcing, contracts, finance and demand.
Explore
Performance Marketing
ApexAIQ
35 agents across seven crews work your Google and Meta accounts in parallel, 24/7.
Explore
Data Privacy & Compliance
DPDP-AID
DPDP Act compliance through true discovery — code, schemas and legacy data parsed for real lineage.
ExploreNext step
See Quillect on your own documents.
Book a free demo of Quillect, or scope a no-cost proof of concept (PoC) on your own data. A senior engineer replies within one business day.